SIGMOD 2027
SALUS: Automated Auditing of NL-to-SQL Benchmarks through Weak Supervision of Multi-Agent Output
Paper
Code
DOI
Abstract
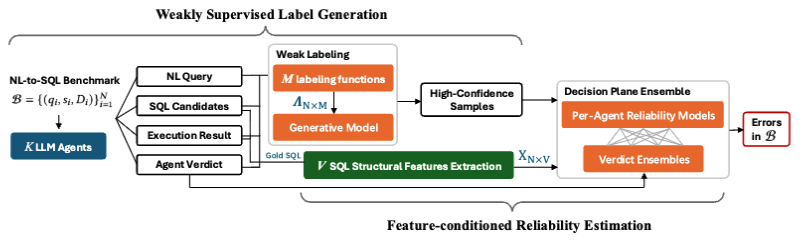
SALUS detects annotation errors in natural-language-to-SQL benchmarks. SQL generated by multiple LLM agents provides complementary weak supervision signals, which are combined to identify high-confidence training examples without human ground truth. A learned decision model then uses query features and agent reliability to audit reference annotations. Evaluations on BIRD and Spider reveal substantial annotation errors and their effects on leaderboard reliability.